JARVIS/ULTRON: Barge-In Voice Assistant with a Live HUD
A Windows voice assistant with always-on VAD, instant barge-in, a Claude or local-model brain, per-sentence streamed TTS and an audio-reactive neural HUD.
Browser VAD to Whisper to a persona-prompted Claude Code or Ollama brain to Kokoro TTS streamed sentence by sentence into a 60 fps canvas HUD; the brain does real work with tools and once fixed its own hearing by downloading a better speech model.
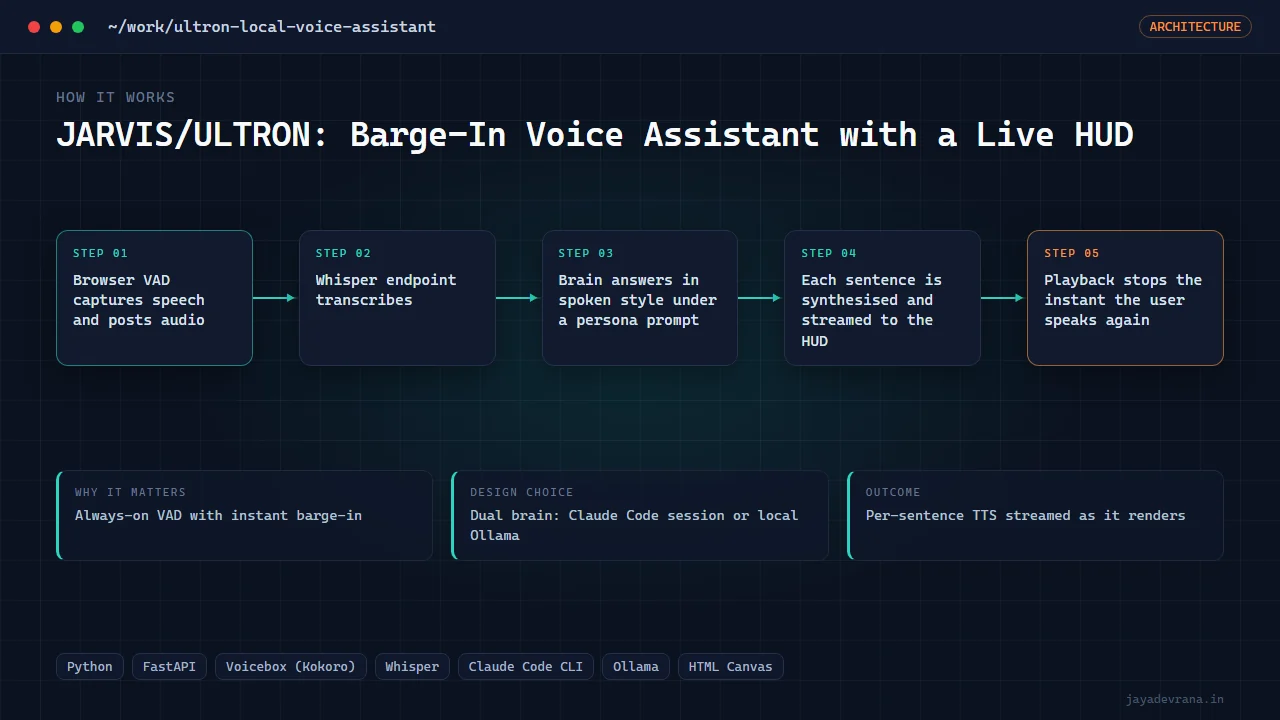
- Always-on VAD with instant barge-in
- Dual brain: Claude Code session or local Ollama
- Per-sentence TTS streamed as it renders
- Brain self-repaired its speech model with tools
I wanted task briefings delivered like a film AI rather than a wall of text, and then a full conversational assistant with no push-to-talk. Phase one renders a self-contained HTML HUD with an audio-reactive canvas, a mission log and subtitles, voiced by a British-accented Kokoro preset through a headless Voicebox server; "real-time video" here means a live 60 fps canvas, not diffusion video.
Phase two is ULTRON: a FastAPI server and browser page with always-on voice activity detection and barge-in (the user's speech instantly stops playback), transcription via a Whisper endpoint pinned to the large-v3-turbo model after the base model misheard, a brain that is either Claude Code continuing one session with a persona prompt or a local Ollama model, and per-sentence Kokoro synthesis streamed to the page as clips finish, pitched down and echoed for the character. The HUD is a 380-node orange brain point cloud with firing synapses that frenzies while thinking and pulses with the voice.
The brain has tool access and verified it by creating files unattended; asked to fix its own hearing, it downloaded and activated the turbo speech model. The microphone requires a real browser on a secure origin, with a text fallback everywhere.
How it works
- Browser VAD captures speech and posts audio
- Whisper endpoint transcribes
- Brain answers in spoken style under a persona prompt
- Each sentence is synthesised and streamed to the HUD
- Playback stops the instant the user speaks again