Self-Hosted SEO Stack Without Admin Rights or Docker
OpenSEO, SerpBear, LibreCrawl and Matomo running natively on a locked-down Windows PC, with a cookieless analytics relay through shared hosting.
Portable PHP and MariaDB for Matomo, a queue-and-sync relay that keeps raw hits off the public host, a custom SERP scraper added to SerpBear, hourly self-healing via user-level scheduled tasks, and audit findings fed back into the sites' builders.
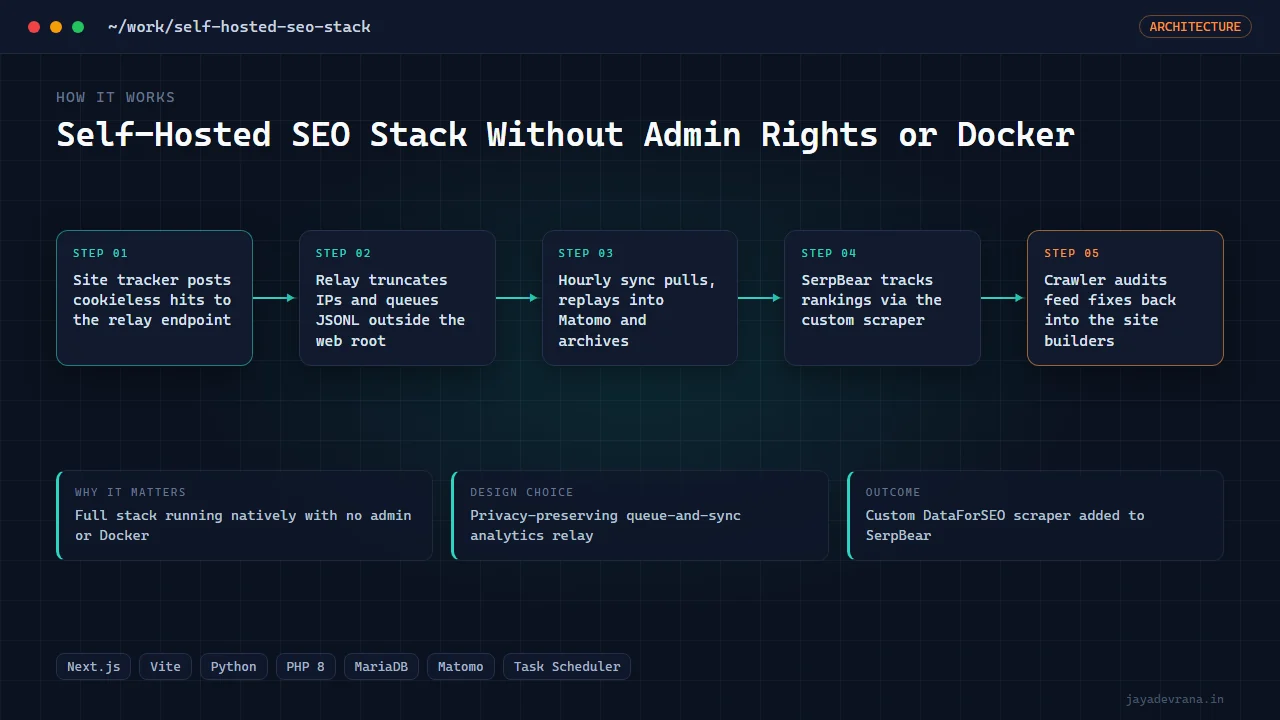
- Full stack running natively with no admin or Docker
- Privacy-preserving queue-and-sync analytics relay
- Custom DataForSEO scraper added to SerpBear
- Audit findings turned into site-builder changes
The machine has no administrator rights, so WSL, Hyper-V and logon-triggered tasks are unavailable and Docker is out. The stack runs natively instead: a Vite dev server for OpenSEO, a Next.js build plus cron worker for SerpBear, a Python crawler, and Matomo 5 on a portable PHP built-in server with a portable MariaDB. A start script restarts whatever is down and an hourly user-level task runs it along with the analytics sync and archiving.
The analytics relay is the interesting part. Site pages load a cookieless tracker that posts to a tiny PHP endpoint on the shared host; it truncates the IP and appends JSONL to a directory outside the web root. The local sync pulls finished-hour files through a key-protected endpoint, replays them into Matomo with original timestamps and IPs, and deletes them on success. Goals are WhatsApp, form, mail and phone clicks, and the sites' cookie and privacy policies describe exactly this.
When the SERP API signup was refused, a DataForSEO scraper module was written into SerpBear and the same key feeds OpenSEO. A crawl audit of the company site produced concrete build changes: a 60-character title ladder, clipped descriptions, legacy link rewriting across 8,691 guide links, and noindex on near-duplicate pages.
How it works
- Site tracker posts cookieless hits to the relay endpoint
- Relay truncates IPs and queues JSONL outside the web root
- Hourly sync pulls, replays into Matomo and archives
- SerpBear tracks rankings via the custom scraper
- Crawler audits feed fixes back into the site builders